What is RAG and why does it matter for enterprise AI?
Most organisations deploying large language models hit the same wall. The model is impressive in a demo. It answers questions fluently, drafts content quickly, reasons through problems with apparent confidence. Then someone asks it something specific - about your product margins, your customer contract terms, your operational procedures - and it either makes something up or tells you it does not know.
That is not a model quality problem. It is an architecture problem.
The default behaviour of any LLM is to answer from its training data. That data has a cutoff date, contains nothing proprietary to your business and cannot be updated without retraining the model from scratch. For consumer use cases, this is a minor inconvenience. For enterprise deployment, it is a fundamental limitation.
Retrieval-augmented generation - RAG - is the architectural pattern that solves this. It connects a language model to your actual knowledge at query time, so answers draw on current, specific, authoritative information rather than statistical approximation.
This article explains how RAG works, where it creates genuine commercial value and what separates a well-built RAG system from a fragile proof of concept that never makes it to production.
How RAG actually works
The name is technical. The concept is not.
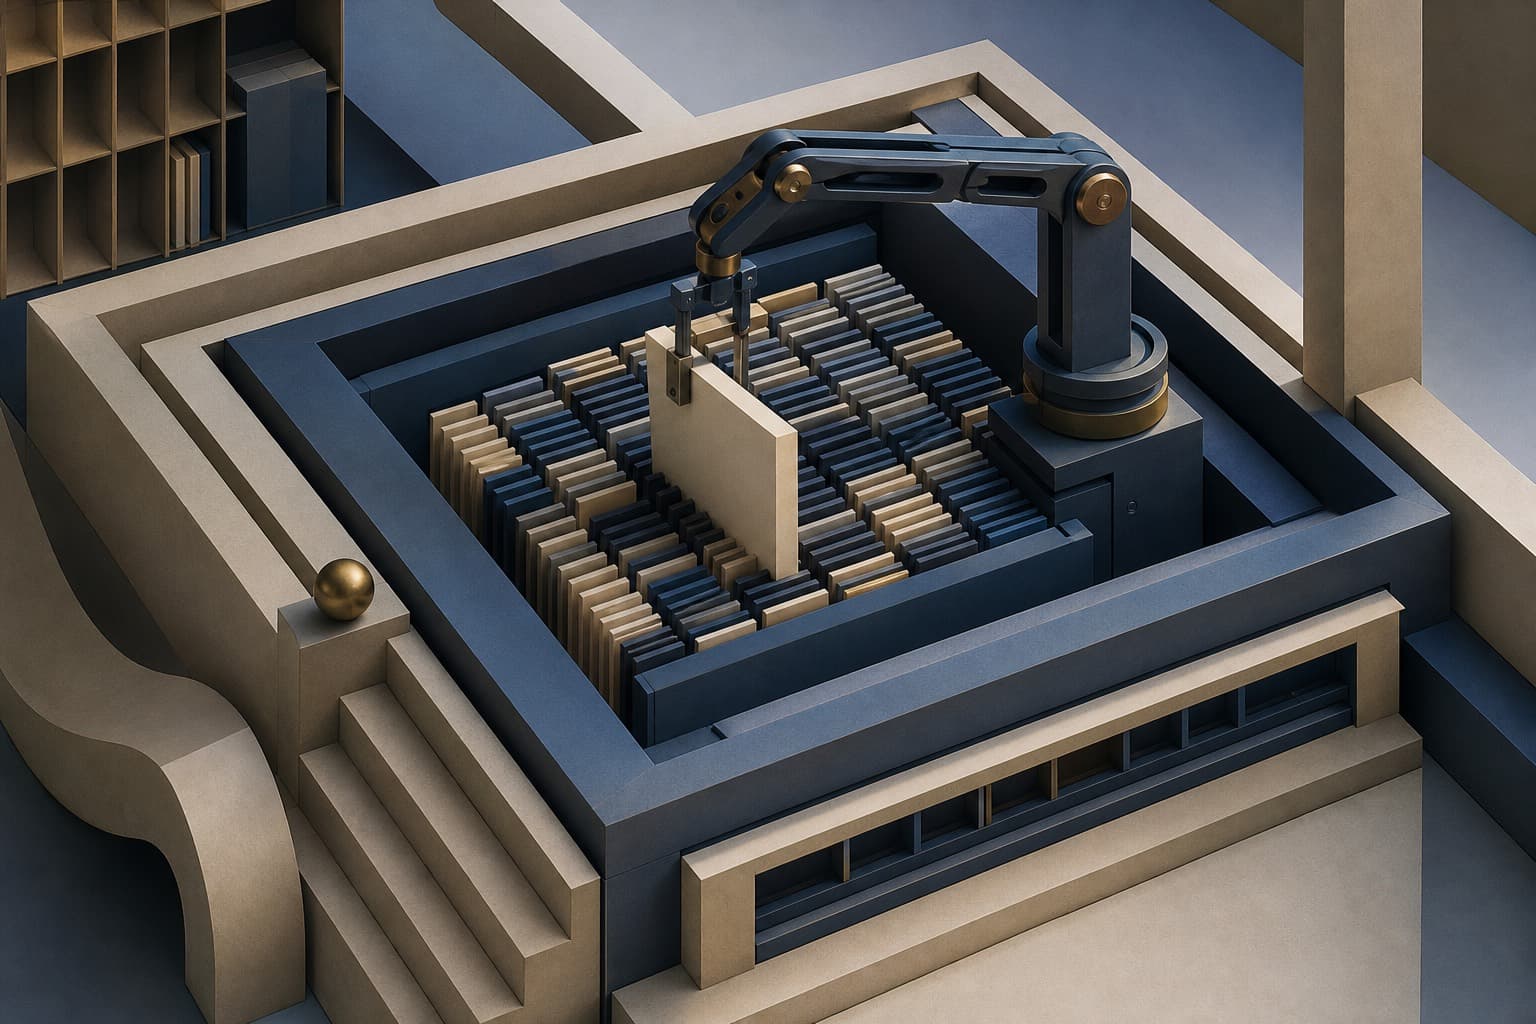
A standard LLM responds to a question using only what it learned during training. RAG adds a retrieval step before the model generates its response. When a user asks a question, the system first searches a connected knowledge base - documents, databases, reports, manuals, whatever you have indexed - retrieves the most relevant chunks of information and passes them to the model as context. The model then generates a response grounded in that retrieved material.
Think of it as the difference between asking a consultant who read about your industry three years ago and asking one who just reviewed your current board pack before walking into the room.
The core components are:
- A document store - the indexed repository of your internal knowledge, whether that is SharePoint documents, CRM records, technical specifications or financial reports
- An embedding model - which converts text into numerical representations that capture semantic meaning, enabling search by concept rather than keyword
- A retrieval mechanism - typically a vector database that matches the user's query against indexed content and returns the most relevant passages
- The language model itself - which synthesises a coherent, contextually appropriate response from the retrieved material
This is not a trivial engineering task, particularly at enterprise scale. Data quality, chunking strategies, retrieval precision and prompt construction all affect whether the system produces reliable answers or confident-sounding nonsense. But the architecture is now mature, well-tested and deployable without building anything from first principles.
Where RAG creates commercial value
The value of RAG is not abstract. It shows up in specific workflows where the cost of generic or outdated answers is measurable.
Internal knowledge retrieval. A professional services firm with 400 staff and twelve years of project documentation cannot effectively surface what it knows. Consultants re-research problems that have already been solved. Partners answer questions from memory rather than from the firm's actual methodology library. A RAG system built over that documentation changes the economics of knowledge retrieval. The answer to "how did we approach a comparable restructuring in the logistics sector" becomes a thirty-second query rather than a thirty-minute conversation with three senior people.
Operational and compliance question-answering. A regulated financial services business might have several thousand pages of internal policy, product documentation and regulatory guidance. Customer-facing staff need accurate answers quickly. RAG enables a system that retrieves the authoritative policy text, surfaces the relevant passage and generates a response that can be traced directly back to source. That traceability matters as much as the speed.
Commercial intelligence. A £700m manufacturing business with a complex product catalogue, variable pricing and multiple distribution channels cannot give its sales team a single place to ask questions about margin, availability and competitive positioning. RAG over commercial data - connected to live reporting through a system like Quantsole - means those questions get answered in natural language from current data, not from a spreadsheet someone emailed last Thursday.
The common thread is this: the value is not in the language model. The value is in connecting the model to the right information at the right moment.
Why most enterprise RAG deployments underperform
Building a RAG prototype is straightforward. Building one that performs reliably in production, across varied query types, against messy real-world data, is considerably harder.
The failures tend to cluster around three issues.
Garbage in, garbage out. RAG is only as good as the content it retrieves. If the underlying document store contains contradictory versions of the same policy, outdated product specifications or poorly structured data, the model will retrieve the wrong content and generate responses that are wrong with high confidence. The data engineering problem does not disappear because you have added a language model on top of it.
Retrieval precision at the edges. Standard vector search works well for clear, specific queries. It degrades when questions are ambiguous, when the relevant information is spread across multiple documents or when the query uses different terminology than the indexed content. Production RAG systems need re-ranking, hybrid search strategies and query expansion to handle the full range of how real users actually ask questions.
No feedback loop. Most early RAG deployments have no mechanism for measuring whether the answers are actually correct or useful. Without evaluation infrastructure - tracking retrieval relevance, answer accuracy and user satisfaction - there is no basis for improvement. The system either gets quietly abandoned or continues producing errors that nobody is measuring.
A useful diagnostic question: if you deployed your RAG system tomorrow, how would you know in three months whether it was working?
What good RAG architecture looks like in practice
A well-built enterprise RAG system has five properties that distinguish it from a prototype.
- Curated, governed data sources - not every document your organisation has ever produced, but a defined, maintained corpus of authoritative content with clear ownership and update processes
- Hybrid retrieval - combining semantic vector search with keyword search and metadata filtering to handle the full range of query types
- Source attribution - every response cites the documents it drew from, so users can verify answers and trust is built over time rather than assumed
- Evaluation framework - automated and human-in-the-loop processes that continuously measure retrieval quality and response accuracy
- Integration with live data - for commercial and operational use cases, static document retrieval is insufficient; the system needs connections to current data through APIs or a BI layer
This is the difference between a RAG system that impresses in a demo and one that becomes infrastructure. The former is built to show a capability. The latter is built to operate at scale, handle edge cases and improve over time.
For organisations deploying agentic AI systems - where autonomous agents need to retrieve, reason and act across multiple data sources - RAG is foundational rather than optional. Eclipse, Rodan's agentic AI framework, is built on this principle: agents that cannot retrieve accurate, current information cannot make reliable decisions.
The cost of getting the architecture wrong
RAG is not experimental. Organisations that treat it as such are not being cautious - they are falling behind while they wait.
The firms building RAG systems now are compressing the time between a question being asked and a reliable answer being given. They are reducing the load on senior people who currently act as human retrieval systems. They are making their existing knowledge assets - the documentation, the data, the institutional memory they have accumulated over years - actually searchable and useful.
The organisations that delay because the architecture seems complicated will face a straightforward problem in eighteen months: their competitors will have systems that know their business and can answer questions about it accurately and quickly. Theirs will not.
If you are uncertain whether your current data and document infrastructure is ready for a production RAG deployment, the right first step is a structured diagnostic. Rodan runs a focused engagement - typically completed within two weeks - that assesses your knowledge assets, maps the highest-value RAG use cases for your business and identifies the data quality issues that need resolving before any build begins.
Book a diagnostic with Rodan at rodan.io.